
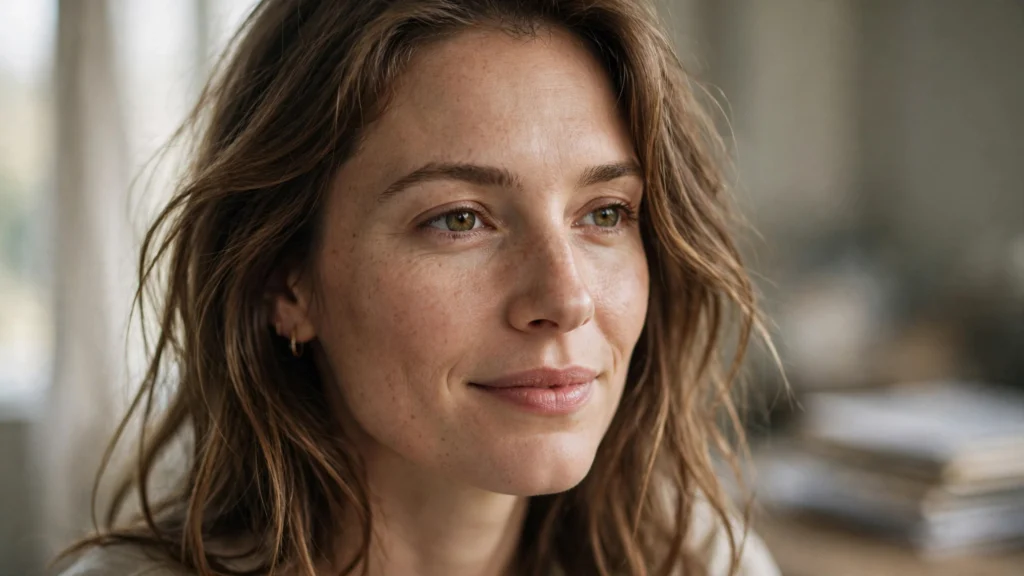
Ask a model for “happy” and you get a theatre kid. Teeth, squinted eyes, head tilt, the whole face performing happiness at the camera like it’s being graded on it. Ask for “sad” and you get the matching poster: drooped everything, maybe a single tear with studio lighting. Neither one survives three seconds in an edit, because real people on camera almost never do that with their faces. Real emotion — the kind a viewer believes — is smaller, physical, and usually halfway hidden.
This took me longer to learn than any camera setting. In my pipeline, expression is written on the storyboard panel before the prompt exists: a held breath, a half-smile that doesn’t reach the eyes, a glance that drops a beat too late. When I board the feeling as a physical note, the prompt inherits something a model can hold. When I type a mood word at generation time and hope, I get melodrama. This guide is the vocabulary and the habits that replaced mood words in my work.
Why Big Emotions Render Fake
There are two reasons big emotions break, and knowing both helps you write around them.
The first is exaggeration pressure. A word like “joyful” or “devastated” has no built-in scale, so the model reaches for the clearest example it knows — the stock-photo version, the emoji version. Stock expressions are performed for legibility at thumbnail size. Your shot doesn’t need thumbnail legibility. It needs continuity with the shot before it, where the same person was neutral. The jump from a natural face to a poster face in one cut reads as a mask swap. Viewers feel it even when they can’t name it.
The second reason is sustain. A big expression is a peak, and peaks are hard to hold. Across an eight-second generation, a wide grin must be maintained by muscles the model is inventing frame by frame. It decays. The smile wobbles, the eyes drift out of sync with the mouth, one side of the face gives up before the other. Small expressions decay too — but they decay into neutrality, which still looks like a person. Big expressions decay into asymmetry. Which looks like an artefact.
There’s a third, quieter problem: emotion words hijack the whole prompt. Write “a terrified woman runs through the forest” and the model spends its attention on performing terror — face, posture, arm flail — at the expense of the run, the forest, and the framing. The emotion becomes the action. If the shot is about the emotion, that trade can be worth it in a tight close-up. If the shot is about anything else, the emotion word just taxed everything else to pay for a face you didn’t need at that size.
None of this means models can’t do emotion. It means they do it the way good screen actors do it: through small, specific, physical choices that a camera can see and a generation can sustain. Your job in the prompt is to write those choices, not to name the feeling they add up to.
Emotion As Physical Detail: Eyes, Breath, Hands
When I stopped writing feelings and started writing bodies, my discard rate on character shots dropped more than from any other single change. The method is simple to state: translate the emotion into three physical channels — eyes, breath, hands — and describe the ones the framing can actually see.
Eyes Carry More Than Mouths
Viewers read emotion from eyes first. The mouth is louder, but the eyes are believed. That’s fortunate, because eye behaviour is also more holdable in generation: a gaze direction, a blink pattern, a slight narrowing. Small movements with clear end points.
Useful eye language includes: “gaze drops to the table,” “eyes flick to the door, then back,” “stares without blinking,” “eyes close for a moment,” “looks past the camera, not at it.” Each of these is filmable, each has a duration, and each implies a feeling without naming it. “Stares without blinking” over four seconds does more for tension than the word “tense” ever will.
Wet eyes deserve a special note because they’re the most abused shortcut in AI video. “Tears streaming down her face” melts more often than it lands — liquid on a moving face, plus a big expression, plus usually head motion. What works at a fraction of the risk is the moment before tears: “eyes glistening, holding back tears, jaw tight.” The viewer’s brain supplies the crying. The model only has to supply a held face. Which it can do.
Breath Is The Emotion Metronome
Breath is invisible in a still and unmistakable in motion. A held breath before speaking. A slow exhale through the nose. A breath that catches. Shoulders that rise once and settle. These cues set the emotional tempo of a shot without touching the face at all — which makes them safe in medium and wide framing, where faces are small anyway.
Breath words that have earned their keep in my prompts: “holds her breath,” “lets out a slow breath,” “breath catches,” “breathing hard, shoulders rising,” “one deep breath, then still.” Notice each one is a small event with a finish. “Breathes nervously” isn’t — it’s a wish wearing a verb’s clothes. Give breath a beginning and an end, same as any other action.
Hands Betray What Faces Hide
Hands are where polite faces get contradicted, and viewers love that contradiction because it feels true. A character can hold a neutral expression while their hands give them away: fingers tightening on a cup, a thumb rubbing the edge of a phone, hands folding and unfolding in a lap.
Hand emotion is riskier to generate than eye emotion, because hands are hands — the contact problem never fully goes away. The compromise that works is simple hand states over hand performances. “Hands clasped tight in her lap” is a state the model can hold. “She wrings her hands nervously throughout” is a repeating complex motion that’ll soften by second three. States hold. Performances decay. Choose the state that implies the performance: grip, pressure, stillness. A perfectly still pair of hands in a tense scene reads as controlled fear better than busy fidgeting reads as anything.
Put the three channels together and a feeling becomes a promptable beat. Not “nervous,” but: “She looks down at her hands, clasped tight in her lap, holds her breath.” That’s one small action chain a model can stage, a storyboard artist can draw, and a viewer can feel. The emotion word never appears, and the emotion is the one thing everyone notices.
The Micro-Expression Vocabulary
Below is the working vocabulary I actually pull from. It’s short on purpose. Every entry has survived repeated use in Seedance and Veo shots, and each one is phrased the way I type it, attached to a subject, in present tense.
- Half-smile: “a faint half-smile that fades.” Safer than any grin, and the fade gives the model an end point.
- Suppressed smile: “trying not to smile, lips pressed.” The effort is the charm, and effort reads at small scale.
- Jaw set: “jaw tight, chin slightly raised.” Anger or resolve without shouting face.
- Brow work: “brows knit for a moment,” “one brow lifts.” Brief, specific, and over before it can wobble.
- Lip press: “lips pressed together, then relax.” Disapproval, restraint, decision — context decides which.
- Swallow: “swallows hard, looks away.” Fear or grief at a fraction of the melting risk of tears.
- Slow blink: “a long, slow blink.” Exhaustion, disbelief, or calm, depending on the scene around it.
- Almost-laugh: “breathes out a short, surprised laugh.” One beat, finished quickly, hard to sustain badly.
- Blank hold: “face still, eyes unfocused.” Shock or dissociation. Stillness is the most holdable expression there is.
- Glance and drop: “meets his eyes, then looks down.” Shyness, guilt, or respect — the drop does the acting.
Two patterns run through the list. First, most entries include a change over time — fades, relaxes, then looks down. A micro-expression with a tiny arc feels performed by a person. A static micro-expression held for ten seconds feels like a photograph with camera drift. Second, none of the entries name an emotion. The feeling is outsourced to the viewer, where it was always going to live anyway.
Build your own version of this list the same way you’d build a verb bank: only from shots that survived your edit. When an expression lands, save the exact phrase with the project file. When one melts twice, retire it without sentimentality. Mine has shrunk over time, not grown, and the shots got better as it shrank. A vocabulary of twelve phrases you trust beats a downloaded list of two hundred you’ve never tested.
Emotion Arcs Inside One Clip
A single clip can carry an emotional change, but the change has to be small, singular, and physically staged. One shift, from one readable state to another, across the duration. Neutral to half-smile. Composed to caught-off-guard. Looking at camera to looking away. That’s the budget. Two shifts — happy, then shocked, then relieved — is three shots pretending to be one, and the middle state always gets smeared.
Stage the arc with a trigger when you can. “She reads the message, then a faint smile spreads” works better than “she becomes happy reading the message,” because the trigger gives the model a before and an after with an event between them. The trigger can be tiny: a sound off-screen, a door opening behind her, a name being called. What matters is that the change has a cause inside the shot, so the model isn’t guessing when to switch faces.
Timing words help, sparingly. “After a moment,” “slowly,” “suddenly” — placed against the shift, one of them, not stacked. A sudden shift wants a short clip or it decays in the hold afterward. A slow shift wants duration to breathe. Match the arc to the length you’re actually generating. In a five-second clip, I’ll often board the arc as two clips instead — the neutral hold and the reaction — and let the cut in Premiere create the timing. A cut is a precise instrument. A prompt is a hopeful one. Put the precision where precision matters.
Repeated warning, because it’s the mistake I still catch in my own drafts: don’t stack an emotion arc on top of a locomotion action and a prop interaction and call it one shot. The arc is the shot. If the character must also walk and carry something, let the face stay near-neutral in that clip and earn the emotion in the close-up that follows. Films have always worked this way. The wide shot establishes, the close-up feels. AI video didn’t change that grammar. It just punishes you faster for ignoring it.
Matching Expression To Shot Size
Expression writing that ignores framing wastes the prompt’s most expensive words. The rule is simple: only describe what the shot size can show, and let the body carry the rest.
In a wide shot, faces are punctuation. Nobody can read a half-smile at fifteen metres, in generation or in life. Emotion in wide framing lives in posture and pace: shoulders up or dropped, steps slowing, a stop mid-stride, a turn that hesitates. Write posture. “She stops halfway across the square, shoulders dropping” tells the whole story at that distance. Any face words you add are tokens spent on pixels the viewer will never see.
In a medium shot, you get gesture and breath. Head turns, hand states, the rise of shoulders — this is breath-and-hands territory, with glances as accents. Keep face language to direction (looking at, looking away) rather than configuration.
In a close-up, the micro-expression vocabulary earns its place. This is where “eyes glistening, jaw tight, breath held” becomes the entire performance, and it works because the model’s attention and the viewer’s attention are finally on the same square inch of screen. It’s also where restraint matters most, because close-ups magnify decay. A small expression decaying reads as a shifting mood. A large one decaying reads as a face coming apart.
One practical consequence: if the emotion matters, earn the close-up in the board. I see creators ask for subtle feeling inside wide, busy prompts and then blame the model’s acting. The acting was never given a stage. Board the reaction as its own panel, close, quiet, one shift — then the prompt can be four lines long and outperform the heroic paragraph that tried to do everything at once. This is also where a frame-by-frame quality check before publishing pays off: expression decay is invisible at full playback speed and obvious the first time you step through the close-up slowly.
There’s a consistency angle too. Across a sequence, keep the character’s emotional baseline worded identically — same neutral description in every prompt — and vary only the beat. If shot 3 calls her “calm” and shot 7 calls her “stoic” and shot 9 says “expressionless,” the face drifts along with the vocabulary. Consistency of face, like consistency of wardrobe, starts with consistency of wording, a point the broader character consistency guide makes for identity and which applies just as well to temperament.
Restraint: The Professional Default
If you take one habit from this article, take this one: default to less. When unsure how much emotion to write, write half of what you were about to write, generate, and look. You can always board a bigger reaction as the next shot. You can’t subtract melodrama from a melted generation.
Restraint isn’t flatness. A held, nearly neutral face over the right line of dialogue, or over silence, is one of the strongest things short-form video can do — because everything else on the platform is performing at full volume. The creators whose AI work looks expensive are, in my observation, mostly doing this: small faces, clear actions, specific light. The ones whose work looks generated are asking for big feelings in big words and getting big artefacts in return.
There’s a workflow reason restraint wins in a pipeline like mine. Subtle expressions cut well. A half-smile at the end of one clip and a neutral hold at the start of the next sit comfortably across a cut, because the viewer’s eye isn’t tracking a huge facial state change. Melodrama cuts badly — peaks demand to be matched or the sequence feels like it’s lurching between masks. When I’m assembling in Premiere, the restrained takes are the ones that disappear into the story. The big takes announce themselves as generations, every time, no matter how clean they are technically.
So write the body, name one small change, match it to the framing, and let the audience do the feeling. That’s not a limitation of the tools. That’s how screen emotion has always worked. The model is just a very literal actor. Direct it like one: give it something small, true, and holdable to do, and it’ll give you a face you can cut to — which, in the end, is the only compliment that matters.